Pablo Miralles
Running LLMs in low-resource settings
Nov 19, 2025Contents
- General
- FlashAttention
- Mixture-of-experts (MoE)
- Data/model parallelism
- Lower precision, mixed precision and quantization
- CPU offloading
- Training-specific
- Parameter efficient fine-tuning: LoRA and soft prompting
- QLoRA (Quantized Low-Rank Adaptation)
- Optimizers with smaller states
- Accumulate gradient batches
- Gradient checkpointing
- Gradient/optimizer state sharding
- Inference-specific
- KV Cache
- Paged attention
- Speculative decoding and draft models
- Efficient batching and scheduling
- LoRA for multi-model serving
In this post I try to create an index of the main ideas I have found to be able to run Large Language Models in my low-resource servers, and to run them as efficiently as possible. The point is not to explain every technique in-depth, but to provide an index with high-level descriptions. I have decided to divide them into three categories: general, training-specific and inference-specific optimizations.
General
FlashAttention
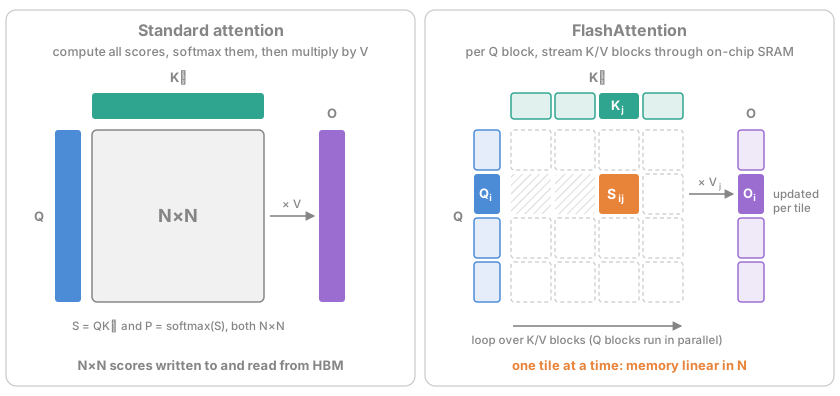
FlashAttention is an algorithm to compute
\[\mathrm{Attention}(Q, K, V) = \mathrm{softmax}\left( \frac{QK^T}{\sqrt{d_k}} \right)V\]efficiently in GPUs. As you probably know, this formula is quadratic in the input sequence length, making it problematic with very long sequences. FlashAttention remains quadratic in execution time, but avoids materializing the full $N \times N$ attention matrix in memory by computing the result in small tiles of $Q$, $K$ and $V$ that fit in the fast on-chip memory of the GPU. For training, it recomputes the attention scores in the backward pass instead of storing them. This makes memory usage linear in the sequence length and, since GPUs are often limited by memory traffic rather than raw compute, also makes attention considerably faster. Newer versions add further optimizations, but I think these are the most important ideas. We rarely need to set this up ourselves, because the main frameworks (e.g. PyTorch’s scaled_dot_product_attention or vLLM) already use FlashAttention-style kernels by default.
Mixture-of-experts (MoE)
A mixture-of-experts (MoE) model splits a neural network into many specialized experts, and uses a gating network (or router) to decide which experts handle each input. In the case of LLMs, this is typically applied in the feed-forward layers. Instead of scaling the MLP layers by widening them, the network uses several MLP experts and routes each token to a few of them (from 1-2 in early models to around 8 in recent ones). This scales the total number of parameters without increasing the compute per token too much. Keep in mind, though, that all experts still have to be stored in memory, so MoE saves compute, not memory.
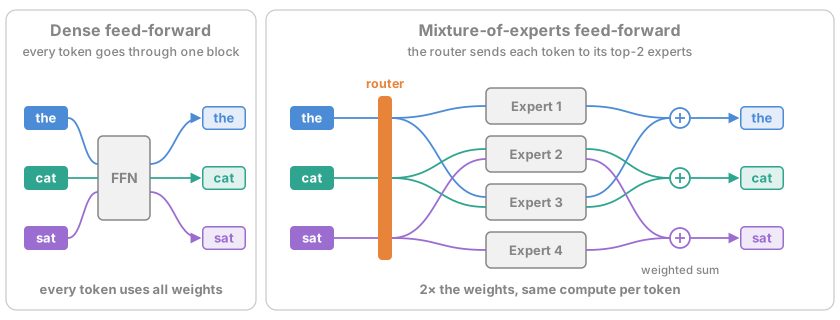
As a side note, during training we must make sure that the tokens are spread across experts to avoid collapsing to a subset of experts. This can be done via an auxiliary load-balancing loss term, adding noise to the gating network that routes tokens, or other ideas.
Data/model parallelism
The concept of parallelism is key both to speed up execution and to be able to run large models that do not fit in a single GPU.
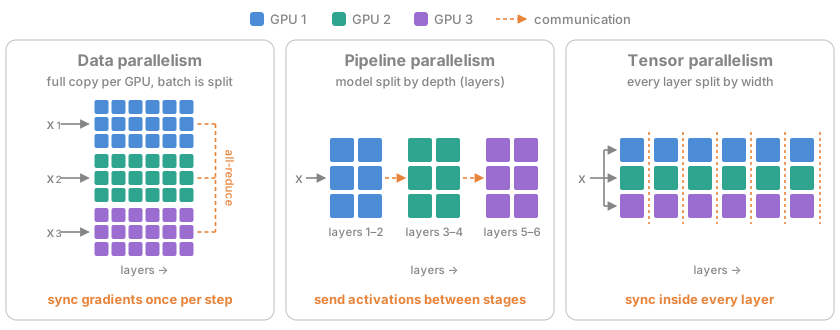
The simplest type is data parallelism, where we store a full copy of the model in each GPU, and the data is sharded across GPUs and processed independently. For training, the gradients must then be synced (averaged) across all devices after the backward pass and before the optimizer step, so that all copies stay identical. This option is great to speed up execution, but it requires being able to fit the model in each device.
In model parallelism, each device holds only part of the model, and the execution of the model is orchestrated across them. We can distinguish two types:
- Tensor parallelism. Each layer of the model is split across the devices. For example, the columns or rows in the weight matrix of a linear layer could be divided by GPU, and the partial results combined (concatenated or summed) across devices.
Pipeline parallelism. The layers are grouped in stages and distributed across the devices. For example, the first device could execute layers 1 to 4, and the second device layers 5 to 8. Of course, there is a dependency between the devices, both in the forward and in the backward pass. To avoid idle time, the batch is divided into micro-batches and the execution is pipelined across them. For example, the first device could execute the first micro-batch, and pass the result to the second device. While the second device processes the first micro-batch, the first device would start processing the second micro-batch.
The following figure compares the execution schedule of pipeline parallelism with and without micro-batching:
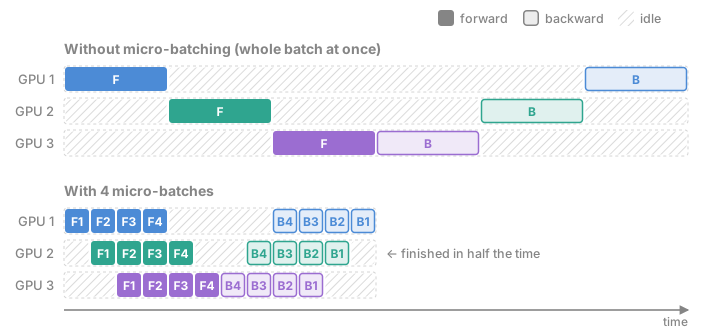
Both options have their advantages and disadvantages. Tensor parallelism enables very big layers to be run and doesn’t need micro-batching, but it needs a lot of communication between devices, requiring high-bandwidth/low-latency interconnects (e.g. NVLink). On the other hand, pipeline parallelism needs much less communication between devices, but requires micro-batching and balanced stages to avoid idleness.
One final note is that all of these types of parallelism can be combined. For example, we could have two copies of the model, each one using three devices via pipeline parallelism, requiring six GPUs in total.
Regarding the implementation, for inference I recommend the vLLM library, which supports tensor, pipeline and data parallelism via simple command line arguments. Training is a bit more complex. The transformers library (through its Trainer and accelerate) offers data parallelism, as well as the device_map="auto" option when loading the model, which splits the layers across GPUs like pipeline parallelism but without micro-batching, so only one GPU works at a time. For a more complete and optimized setup, we would have to use something like DeepSpeed or PyTorch’s FSDP.
Lower precision, mixed precision and quantization
Most operations can be run in 16-bit precision (FP16 or BF16) without problems, reducing memory usage by a factor of 2, and speeding up computations a lot on modern hardware designed for these formats. When available, BF16 is usually preferred, since it has the same range as FP32 and is much less prone to overflow than FP16, at the expense of precision.
Some operations like reductions/accumulations or normalizations are better performed in FP32 to avoid overflow/underflow or to reduce rounding errors. Thus, it is common to keep these operations in 32-bit precision (mixed precision). During training, it is also common to keep master weights of the model and optimizer states in FP32 as well.
A step further is quantization, representing model parameters, and sometimes activations, with fewer bits (e.g., int8, int4 or FP8) instead of 16- or 32-bit floating point. The goal is to reduce the memory footprint and improve inference speed. The speedup usually does not come from faster arithmetic: generating text is mostly limited by how fast the weights can be read from memory, so smaller weights mean faster generation even if they are converted back to 16 bits before each multiplication. The trick here is performing this compression of the model without losing too much accuracy. Very often, we find versions of the top open-source models already quantized with modern techniques like GPTQ or AWQ, so we do not need to worry about it.
CPU offloading
If you are very short on memory but absolutely need to run a large model, you can offload tensors to CPU, and swap them around with the GPU to complete all computations. However, I highly recommend against it, because memory movements are extremely slow.
Training-specific
Parameter efficient fine-tuning: LoRA and soft prompting
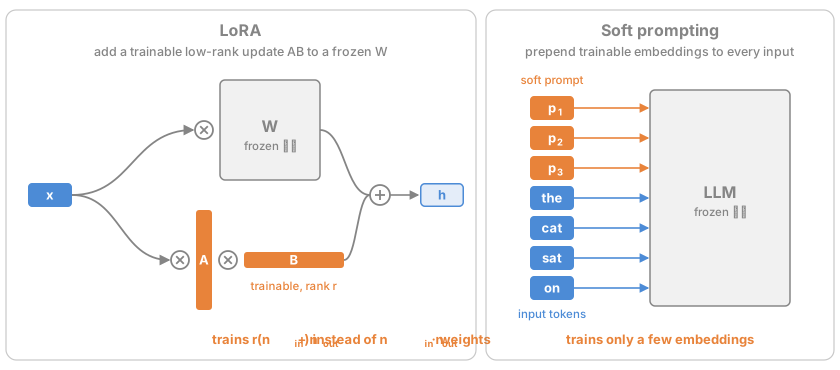
In language modeling, we typically start from a pre-trained model that is then fine-tuned on our downstream task of interest. In most cases, it is sufficient to perform a “reduced” update to the network instead of updating all parameters, greatly reducing memory requirements for the gradients and optimizer states. What is more, given the small amount of labeled data we often have and the high dimensionality of textual data, these reduced updates are less prone to overfitting.
The most common example is LoRA (Low-Rank Adaptation), where a weight matrix $W \in \mathbb R^{n_{in} \times n_{out}}$ is kept frozen and updated with a low-rank term $W_{new} = W + AB$, with trainable matrices $A \in \mathbb R^{n_{in} \times r}$ and $B \in \mathbb R ^{r \times n_{out}}$ and a small rank $r$. This way, we only train $r(n_{in} + n_{out})$ parameters instead of $n_{in} n_{out}$. Another example is soft prompting, where a few trainable embeddings are prepended to all input sequences while the whole model stays frozen.
QLoRA (Quantized Low-Rank Adaptation)
The next step in LoRA is to quantize the frozen base model (to 4 bits in the original paper) while training non-quantized low-rank adapters, achieving very good compression without sacrificing a lot of performance.
Optimizers with smaller states
The Adam optimizer stores $2N$ values for the momentum and second moment running estimates, where $N$ is the number of trainable parameters in the model. We can reduce it to $N$ by switching to SGD with momentum or RMSProp, or reduce it even further with Adafactor, which stores only $n + m$ values for each $n \times m$ weight matrix instead of $nm$. The tradeoff in all cases is potentially less stable training and slower convergence.
Another option is to keep Adam but store its states in lower precision. 8-bit optimizers quantize the momentum and second moment to 8 bits, cutting their memory by a factor of 4 (from 8 bytes per parameter to 2). To preserve accuracy, the states are quantized in small blocks, each with its own scale, so that a few outliers do not ruin the precision of the rest. At each step, they are dequantized to 32 bits, updated, and quantized again. It is easy to use through the bitsandbytes library (e.g. optim="adamw_bnb_8bit" in the transformers Trainer).
Accumulate gradient batches
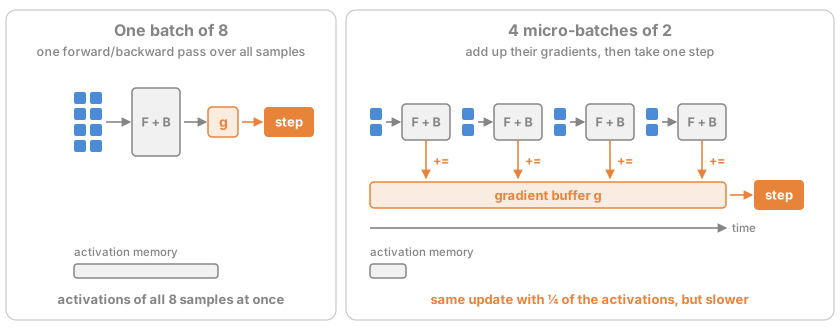
Instead of using a large batch size, we can instead use a small batch size and accumulate the gradient for multiple batches before performing an optimization step. This is equivalent thanks to the linearity of the gradient operator, except in models that include batch level operations (e.g. batch normalization), which are rare in language models. With this, we trade off training speed to reduce memory usage, which is often the stricter limiting factor.
Gradient checkpointing
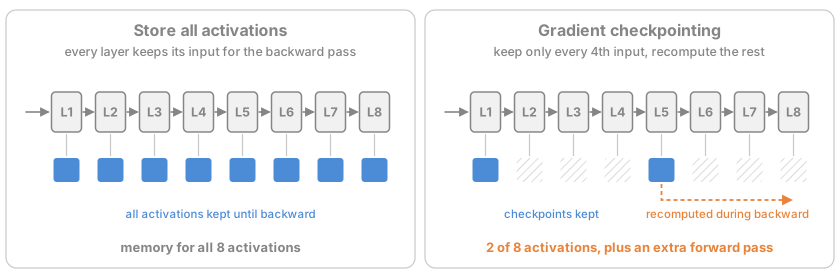
During the forward pass, it is common to store all intermediate activations, since they are needed in the backward pass, to avoid wasteful recomputation. However, this is undesirable when the bottleneck is the GPU memory available. Gradient checkpointing stores only a few of them (e.g. the input of each layer) and recomputes the rest during the backward pass, trading extra computation for a large reduction in memory.
Gradient/optimizer state sharding
While training in a data parallel setting, each GPU contains a copy of the gradients and optimizer states for all parameters. However, this is a bit wasteful, and we can shard (divide) these vectors across GPUs at the expense of some communication overhead. This is the idea behind DeepSpeed’s ZeRO and PyTorch’s FSDP, which can even shard the model parameters themselves.
Inference-specific
KV Cache
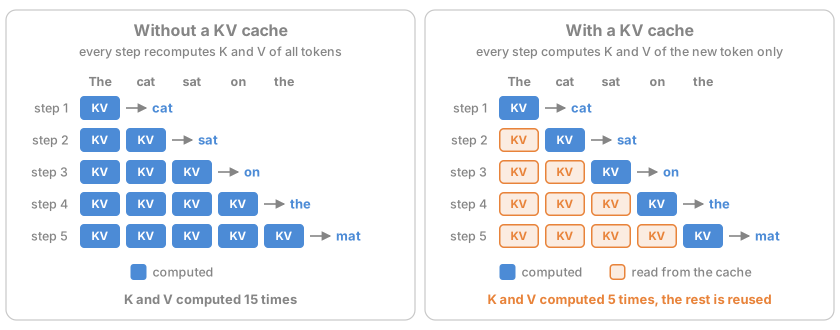
Autoregressive models use a causal attention mask that blocks each token from attending to future tokens. As a result, when generating text one token at a time, newly produced tokens don’t influence the earlier ones, only the other way around. This means we don’t need to redo computations for previous tokens. However, the new token still depends on earlier tokens through their attention keys and values. To avoid recomputing these for every step, we store the keys and values of all previously generated tokens in a KV cache. During each new forward pass, the model retrieves these cached representations and only performs computations for the new token, greatly speeding up generation. The price is memory: the cache grows with the sequence length and the batch size, and can take up more GPU memory than the model itself. Regarding the implementation, this is already done in the typical generation libraries (e.g. transformers or vLLM).
Paged attention
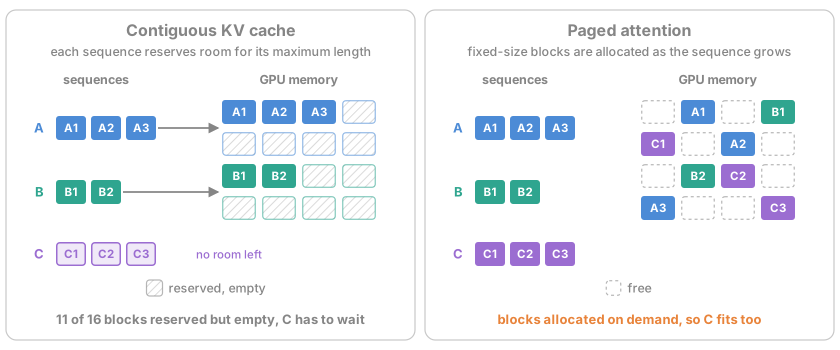
Paged attention implements a type of paged virtual memory for the KV cache in GPU memory. The cache is split into small fixed-size blocks that are allocated on demand, removing the need for large contiguous blocks for long sequences and reducing wasted memory. This is implemented in vLLM.
Speculative decoding and draft models
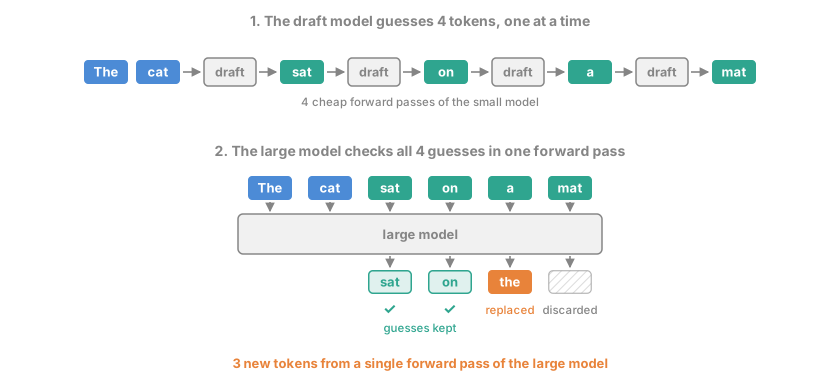
Speculative decoding pairs a large language model with a smaller, faster “draft model”. The draft model predicts several upcoming tokens, and the large model then checks all of them in a single forward pass, accepting the ones that agree with what it would have produced itself and discarding the rest. This allows the system to generate multiple tokens per forward pass of the large model instead of one at a time, significantly reducing latency while producing the same output distribution as the large model alone.
Efficient batching and scheduling
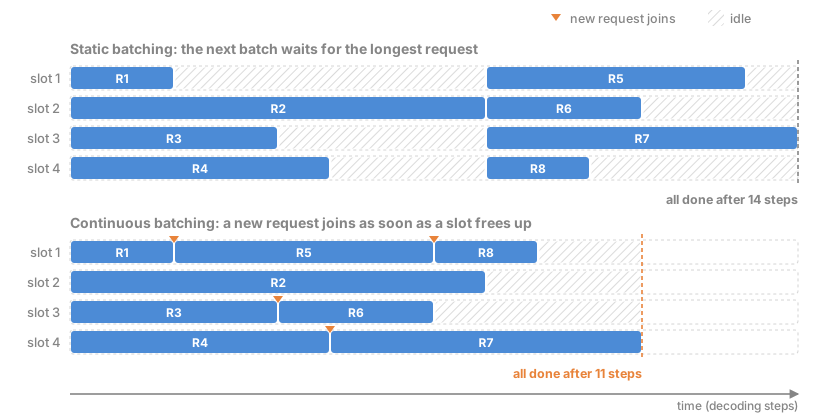
vLLM implements an efficient scheduling algorithm (continuous batching) where new requests made to the model are dynamically added to the current batch, and completed generations are dynamically removed from the batch as well, instead of waiting for the whole batch to finish. This greatly improves resource utilization.
LoRA for multi-model serving
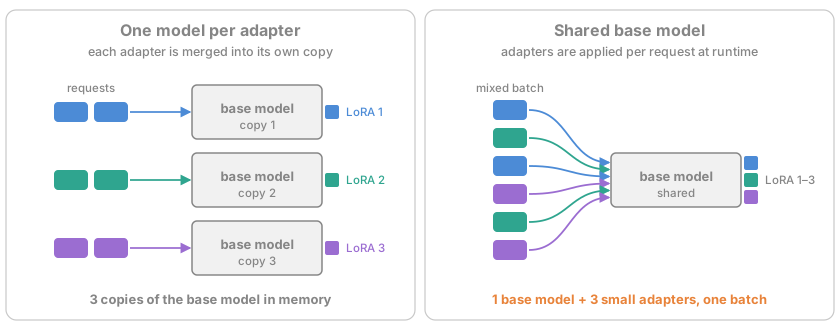
When serving the same base model with several LoRA adapters on top, you can share the common base in GPU memory and apply the right adapter for each request at runtime, even within the same batch, making it very efficient to deploy. This is also implemented in vLLM.